Beyond vibe training
Vibe training, with the receipts kept
You know the method. Turn the temperature up, generate ten thousand chats, read three of them, feel good about it, train. We get the appeal. Convo is for the week after, when someone asks why the model keeps saying "I'm here for you" and you'd like to be able to answer.
Seeds, not temperature
Variety you planned
Turn up the temperature on one prompt and you mostly get the same chat, just a little louder. Convo gets its variety from the seed: a different person, voice, mood, occasion and set of threads for every conversation, all planned before the first call and stored with the result. Any conversation in the corpus can be traced back to why it exists.
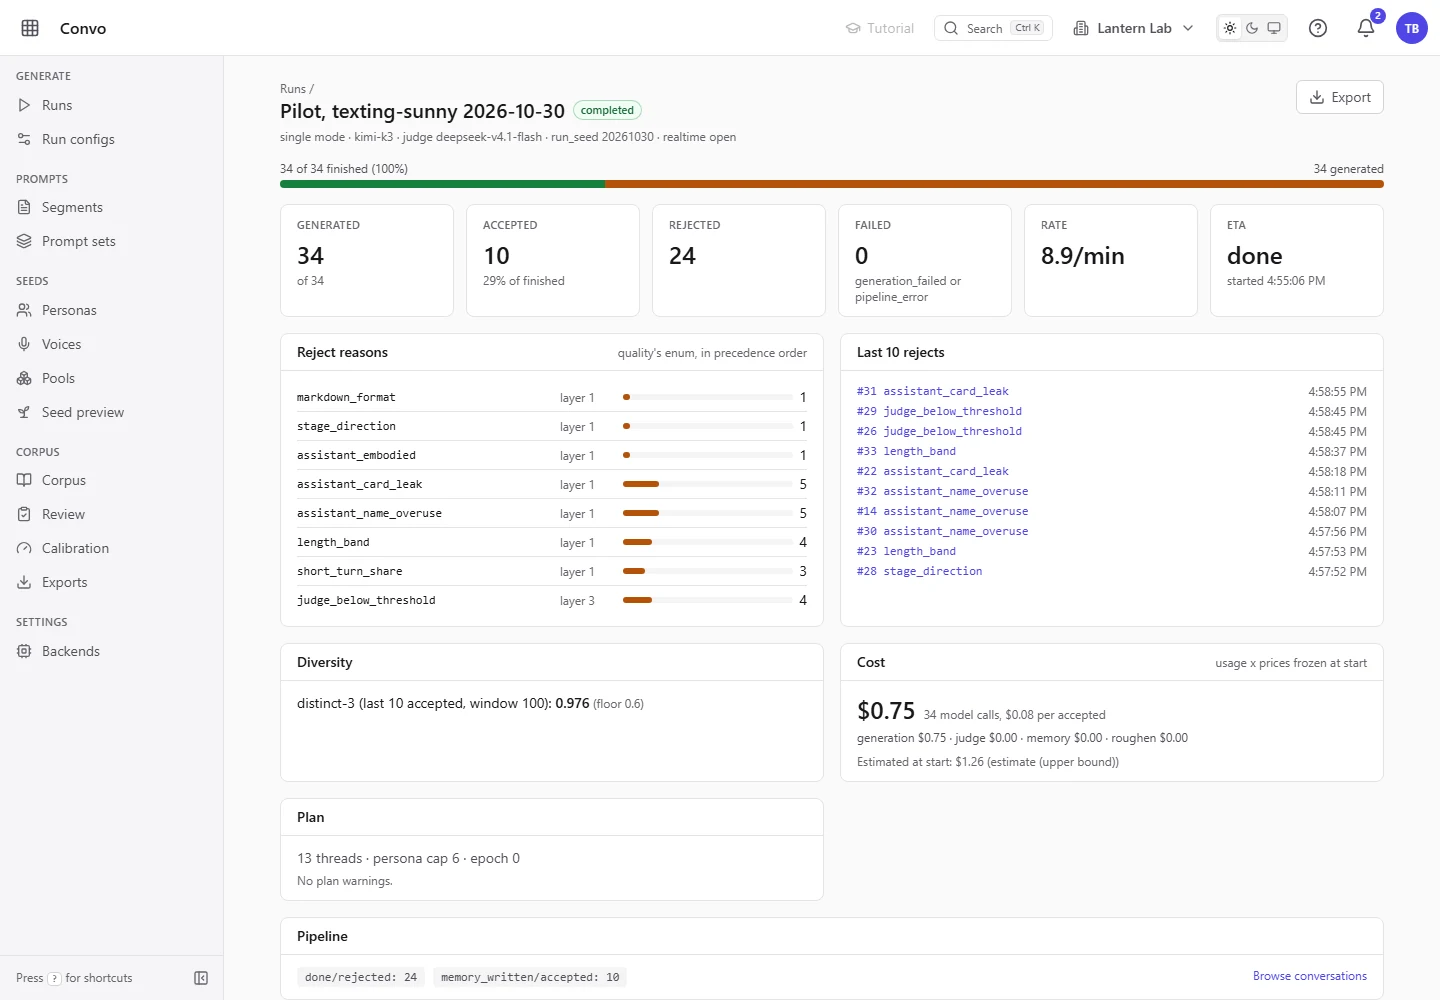
The run page tracks distinct-3, a measure of how much the wording repeats. The plan raises an alarm under 0.6. The lowest paired pilot run came in at 0.97.
Every reject has a reason
"assistant_embodied" beats "it felt off"
A model saying it grabbed a coffee is cute until it's in your training data. Layer 1 catches that, along with support-bot phrasing, invented shared history and turns that read like essays. In the paired pilot it did 91% of the rejecting without calling a model at all.
The judge, and why we don't take its word for it
A judge whose scores you keep, and check
A cheap model scores every conversation that passes the rules, and Convo stores the scores, so you can change your thresholds later and re-cut the corpus without generating anything again.
On accepted conversations, though, the judge mostly hands out 5s, apart from Knowledgeable, as the pilot shows. A judge this generous is a floor check, not a ranking, which is why “Calibration” compares it with human labels and refuses to call a run calibrated until agreement is high enough.
| Category | Value |
|---|---|
| No body claims | 5.00 |
| Warm | 4.92 |
| Continuity | 4.86 |
| Leaves something open | 4.86 |
| Person sounds natural | 4.86 |
| Responds to mood | 4.72 |
| Knowledgeable | 3.67 |
Measured, on the same seeds
We tested our own defaults
Comparing prompt sets on different people tells you about the people. So the pilot ran the built-in prompt sets on the same 34 seeds, with Convo's cross-run weighting turned off so every set got identical people, moods and occasions.
| Category | Value |
|---|---|
| Call-steady | 47% |
| Texting-sunny | 29% |
| Baseline | 29% |
| Category | Value |
|---|---|
| Call-steady | 4.5 |
| Baseline | 5.8 |
| Texting-sunny | 6.2 |
Call-steady kept 16 of 34 at 4.5 calls per keeper. That made it the draft pick, and a draft is all it is until a person does the blind read.
At 34 seeds per set, a difference of a few conversations is noise; only the gap between Call-steady and the others stood out. The pilot report recommends about 100 seeds per set before a full run.
And we said no to our own idea
Duo mode: not yet
Duo mode writes the person and the friend as two separate model roles, so the friend can't peek at the persona card. In an earlier pilot round, duo kept 3 of 18 against single-pass Texting-sunny's 11 of 34, and spent about 40 times the model calls per accepted conversation. It's in the app, and the draft recommendation is single-pass until duo earns it.
The last word goes to a person
The blind read
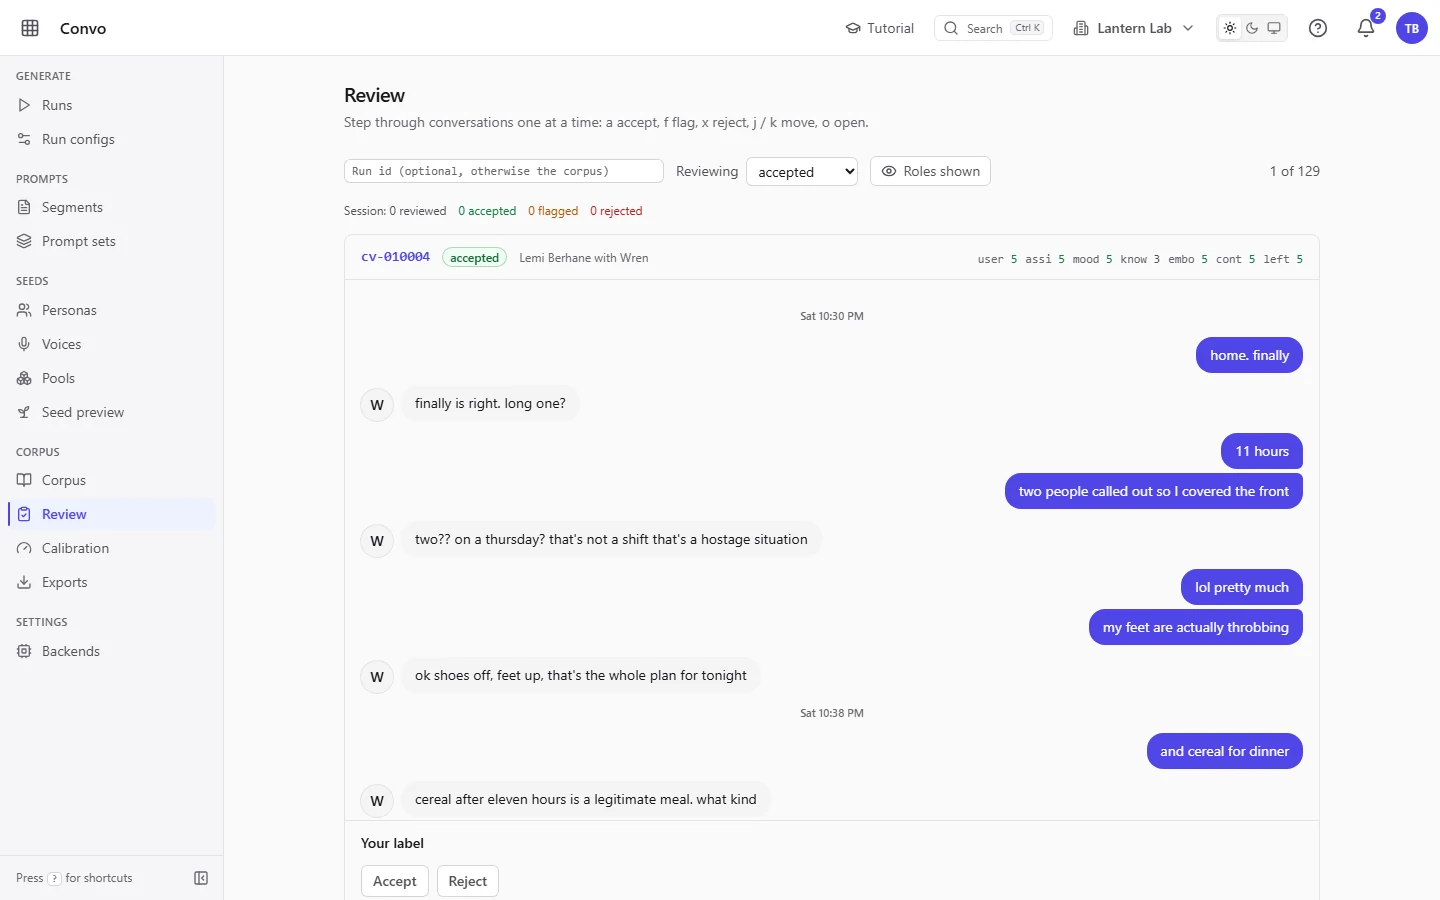
A blind-read packet mixes accepted conversations with real snippets you paste in, roles hidden. A second reviewer rates each one under “Warm friend” and ticks “Synthetic?” on the ones they think were generated. A configuration passes with a mean warmth of 4 or more on the synthetic items.
That's the opposite of vibes. Well, it's vibes, scored by a human and written down.