Models and cost
Know the bill before you start the run
Convo stores the price of every model on its backend, estimates a run before it starts, asks before an expensive one, and can wait for cheaper hours. A model on your own machine or your network has no per-token bill at all.
What 1,000 accepted conversations cost
The number that matters is per accepted conversation, because rejected ones cost money too. On these estimates, kimi-k3 costs about 2.6 times what glm-5.3 does for the same thousand keepers. That's why the default writer is glm-5.3 rather than kimi-k3, which has to win the blind read to justify its price.
| Category | Value |
|---|---|
| deepseek-v4.1-flash | $4.99 |
| deepseek-v4.1-flash, off-peak | $2.49 |
| glm-5.3 | $21.33 |
| kimi-k3 | $54.70 |
Generation cost only, single mode, at Ollama Cloud's published standard rates (2026-10-30), using the token use and 42% acceptance rate measured on 238 pilot generations with kimi-k3; excludes judging, memory and roughening calls and any cache discount. Other models assume the same token profile.
Before you start
An estimate, a threshold and a confirm step
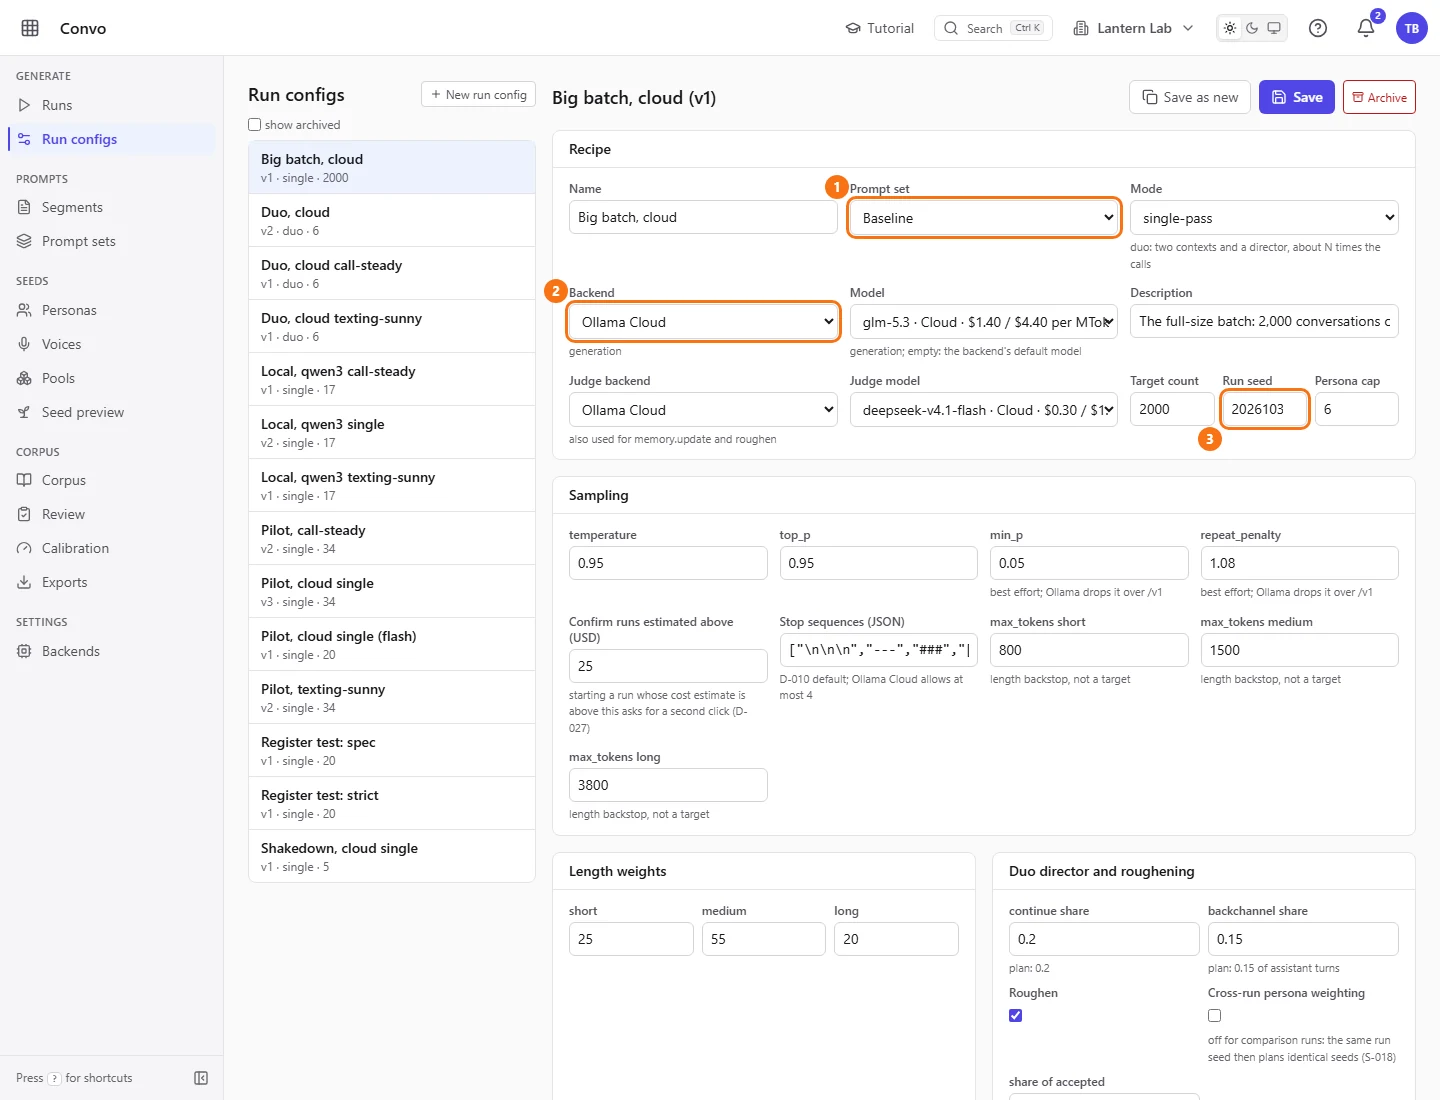
Starting a run shows its cost, labelled “estimate (upper bound)” because some providers cache part of the prompt and bill less than they report. A run estimated above $25 asks you to confirm first. The threshold is a setting on the run config.
AI agents driving Convo through its MCP server get the same treatment: starting a run only stages it, with the estimate and the cost per accepted conversation, until a confirm call approves that amount.
Off-peak
Let the run wait for cheaper hours
deepseek models on Ollama Cloud cost 50% less on weekdays outside 12:00 to 18:00 UTC, and all weekend. If you start a run on a model with off-peak prices during peak hours, “Start run” offers “Start at next off-peak window”. Tick it and the run waits, queued, until the window opens.
Prices you can see
Stored per model, shown where you pick one
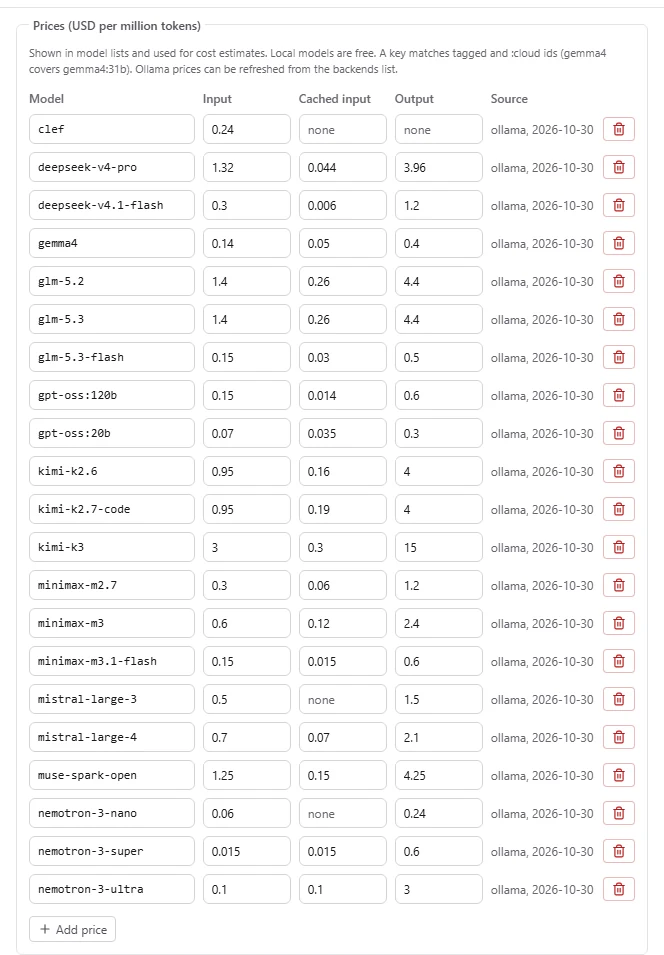
Each backend keeps the published price of its models, and the model pickers show it next to the name. For Ollama Cloud, the backend's Billed usage panel reads the account's own usage report, so you can compare the estimate with what was actually charged.
| Model | Input | Output |
|---|---|---|
| deepseek-v4.1-flash | $0.30 | $1.20 |
| glm-5.3 | $1.40 | $4.40 |
| kimi-k3 | $3.00 | $15.00 |
Local and LAN
Or pay nothing per token
Ollama on your own machine is a built-in backend, and a server on your network shows up as LAN. Their models read “Local · free” in the pickers. In the pilot, qwen3:30b-a3b-instruct-2507-q4_K_M on one GPU kept fewer conversations than kimi-k3 on the cloud. It wrote stage directions and claims of a body more often, and Layer 1 threw those out. For drafting prompts and smoke runs it costs nothing but time.
| Category | Cloud, kimi-k3 | Local, qwen3:30b-a3b-instruct-2507-q4_K_M |
|---|---|---|
| Baseline | 50% | 29% |
| Call-steady | 50% | 35% |
| Texting-sunny | 56% | 41% |
Phase A personas differ between runs; this shows the spread, not a ranking.